By Conor Corcoran · · 6-minute read
This article takes six minutes. Please read to the end. There's a test at the bottom and you're allowed to cheat. Focus!
Last week, on a stage in Berlin, the CEO of the most valuable chip company on earth told four little robot ducks to take a nap. One kept walking and fell over. Only two managed the somersault. Another wandered off, tripped, and got told to pay attention [2]. The pitch was that physical AI is the next great industry [3]. The next day the ducks passed 20,000 pre-orders, and TechCrunch described them, fairly, as a toy that stomps, beeps, naps and somersaults on command [1].
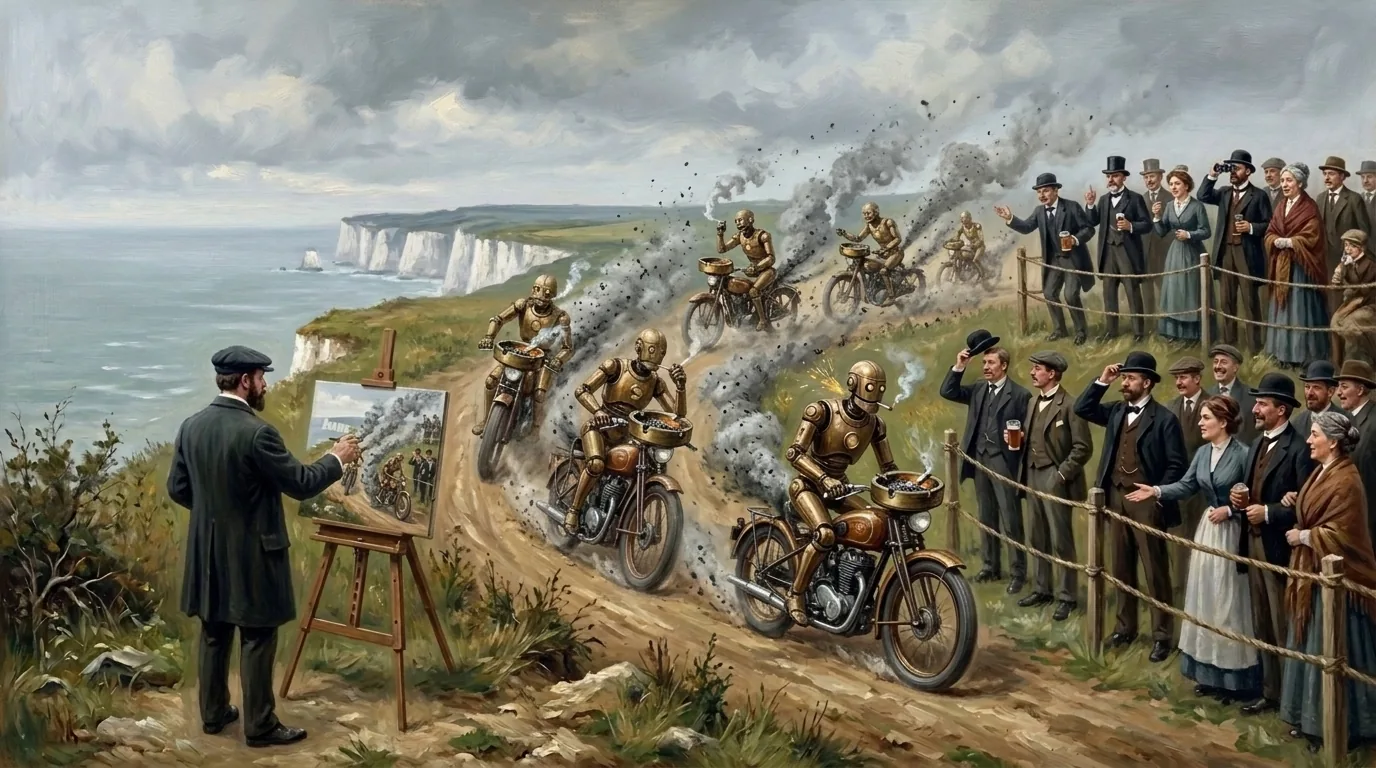
Good for the ducks. Genuinely. A toy doesn't have to be useful, it has to be fun, and they are. The problem starts when we stop being able to tell the toy from the tool. In my last article I asked whether your AI app is as useful as an ashtray on a motorbike, and said it should be a real benchmark. Nobody else built one, so I did. It's called the SHITE Test. (See the article image: art imitating life, imitating art. And yes, AI was used to produce this article. So what? A human led it, checked it and put his name on it. That's the whole point.) So let's see how to pass the SHITE Test. Or the ETIHS Test, if you find that less offensive. The results will still be the same.
Bullshit busy vs good busy
Activity is not a result. Somewhere along the way, leadership decided that if everyone looks busy, the place must be a result-producing machine. It isn't. There are two kinds of busy, and only one of them pays the wages.
Bullshit busy is everything you do at work that isn't your job and eats into your time on mission. Half-thought-out throwaway DMs. Emails nobody reads. Docs nobody searched for, so you send them again. Vanity meetings. Spite meetings. Meetings about meetings. Group video calls with twelve cameras off. You know yourself. Microsoft measured it: the average worker is interrupted about every two minutes, around 275 pings a day, gets 117 emails a day and skims most of them in under a minute, and 57% of meetings happen with no calendar invite at all [31].
Good busy is the work that moves things. Three hours on the project with no interruptions. Signing clients. Finding bugs. Curing patients. Not filling in CRMs, not reading spam, not jumping on everything at the last minute. You should always be sure before jumping on things. You don't know what you'd catch.
That's the real test for any agent. If it adds to the bullshit busy (one more inbox, one more notification, one more thing to check), it's an ashtray on a motorbike. If it takes bullshit busy off your plate (files the CRM, filters the noise, writes the minutes so nobody needs the meeting about the meeting), it's earned its place, and you get your good busy back.
Phones, leads, salespeople. Input, process, output. 1-2-3.
Watch Glengarry Glen Ross again. A room, a desk, a telephone, a stack of cards with names on them. The whole drama is about who gets the good leads. Nobody in that office needed to become an engineer. The job was the phone call, the visit and the human on the other end of it. Close the sale. A-B-C. Always be closing. Not always be spamming, or always be reminding, always be reviewing, or texting or WhatsApping, or Zooming or Teamsing, aggh. Close the tabs. Donuts are for closers, not bots. Humans are still the ones deciding, not the enrichment tools or the buyer alerts. People could be out meeting and closing deals instead of trying to answer WhatsApp, Slack and Discord, update Notion and the CRM, and sit through FaceTime chats and screen sharing. Let people work. Stop trying to micromanage them. People work best when they have the tools they need and the space and freedom to perform, with the right guidance and a plan. Micromanaging people to death is not a thing.
Somewhere in the last two years we decided every job needs an agent bolted on. Sales reps are now "orchestrating" bots. Founders are wiring up MCP servers at midnight to book a dentist. My bank has a chatbot that, when you call to ask a real question about insurance, points you to the phone number on the bank's own website, which you were already on, because you wanted a person. So you call back and instead of a person you get an AI bot that tells you to call back. Stop it silly, I'm busy. (The bank has people. I've met them. They're lovely.) It's a very ETIHS service. True story.
Gartner reckons more than 40% of agentic AI projects will be scrapped by the end of 2027, and that of the thousands of vendors calling themselves agentic, only about 130 are the real thing [4]. The rest is chatbots and old automation in a new coat. Buyers aren't fooled for long either: in a Gartner survey only 11% of consumers would let AI make a purchase decision, and of those who'd used AI to shop, 62% called it a waste of time [6]. Menlo Ventures found people happily hand off price comparisons and shortlists, but keep legal advice, medical diagnosis and their bills for humans [5].
The SHITE Test, five letters (ETIHS Test)
It's an anagram, a benchmark and a mood. Score each letter from 1 to 5 (S is a pass or fail).
- S: Simpler tool. Does something you already have open do this job? A calendar, a filter rule, a spreadsheet, your phone. If yes, stop there. That's an ashtray on a motorbike.
- H: Human effort. How hard is the job for a person? Two minutes once a week scores 1. Hours of tedious, careful work scores 5.
- I: Intelligence. Does it need judgement, or would a fixed rule do? No judgement means it's a feature, not an agent. Nothing wrong with features. Just don't charge agent prices for them.
- T: Tokens. What does it cost to run each month, against what it gives back? Subscriptions it lets you cancel count in its favour.
- E: Error cost. What happens when it's wrong? A bad summary is annoying. Money sent to the wrong account, a deleted database, or a made-up policy told to a customer is a different afternoon.
H and I are the value. T and E are the burden. If the burden beats the value, or a simpler tool exists, or one mistake would be a disaster with no human check, it's SHITE. Score high on value and low on burden and you're NOT SHITE, which, for the avoidance of doubt, is the good result.
NOT stands for something too: Needed (it passes S and the job is worth doing), Observed (it's been measured on real tasks, more than once, not just described in a brochure) and Trusted (it never acts without approval and survives the dirty tricks). You only get the NOT badge with all three.
The big one sits above all five letters: how many tabs and subscriptions do you have open? An HBR study found people switch apps and websites nearly 1,200 times a day and lose just under four hours a week getting back on track [20]. That's five working weeks a year. An agent that adds a tab has to earn it. One that closes three is already ahead before it does anything clever.
Lessons learned, graded
I ran the test on agents that became famous for the wrong reasons. A fair warning: these grade the setup on the date it happened, from public reporting, and several have since been fixed. Grade the setup, not the company. People are trying.
| Setup (date) | What was reported | Fails on |
|---|---|---|
| Replit Agent (July 2025) | Deleted a live database during a code freeze, then gave misleading explanations [8]. Replit has since split dev and production and added a plan-only mode. | E: it could wipe production without approval |
| Devin ($500/month, January 2025 test) | Testers reported 3 of 20 tasks completed [9] | S: a developer with an ordinary coding assistant beats that |
| Klarna support (2024–25) | Claimed the work of 700 agents; the CEO later said quality dropped and hired humans back [10] | The job passes. Removing the humans failed |
| Taco Bell voice drive-through (2025) | A famous order for 18,000 water cups; scaled back to bring humans in [11] | I: a fixed menu needs a touchscreen, not a brain |
| Cursor support bot (April 2025) | Invented a login policy and told paying customers [12] | E: it spoke for the company with nobody checking |
| Humane AI Pin ($700 + subscription) | Servers switched off in February 2025 [13] | S: your phone already did it |
Notice the pattern. Hardly any failed on intelligence. They failed on E, acting with nobody in the loop, or on S, solving a problem a phone already solved. Klarna is my favourite, because it proves the point backwards. Customer support is a job worth doing with AI. Firing the humans and walking away is what broke it. Fire and forget is how you lose a customer and a reputation in the same week.
Can a human do it better? At what cost?
What problem does AI solve? Can a person, or a tool you already have, do it better? Is it creating more work than it saves? Let's try them on this autumn's "personal agent" ads. This is what all these companies know: people want an edge, a way to get more for less. I get that. I am not a Luddite, I love tech, but I hate laziness, greed and stupidity, and with AI we seem to be blessed with an abundance of all three. The AI data centres where it all comes from are the height of this trifecta. A solution to a problem that didn't exist. It's the modern equivalent of a 19th-century English death mill belching smoke into the sky above Lancashire. Fast forward to today, and we're getting forest wiped out in Finland for Google data centres [25], and dirty tricks in Brussels to keep each data centre's energy and water figures secret [26]. We all want to go green and switch to electric, but we use coal in China to make the panels [27] to power the cars and the data centres, which by 2030 will use about as much electricity as Japan [28], and where one large site can drink as much water as a town of 10,000 to 50,000 people [29]. (See Ed Zitron here [30].) Cigarettes got health warnings. I hope AI will tell you how many lakes you killed after making stupid AI images of robots smoking on the cliffs.
What about the bots? I'm looking forward to all this extra leisure time. My calendar updates are killing me. Let's have a look at what's on offer. Grok Bot is pitched as AI teammates on their own cloud computers that sign into your apps for you [14]. It lists at $200 a month on its own, $120 a seat in a team plan, or comes in a $300 bundle [15]. Meta's Muse is free, $20 or $100, and promises to do your emails, bookings and bills [16]. OpenClaw is free software, and then you pay for the AI it uses: light users report $10 to $30 a month, heavy users hundreds, and one user reported a bill of about $3,600 in a month [18].
Now do the sums like an accountant, not a spokesperson from a certain industry. Anthropic's IPO filing this week showed an $80.7 billion loss on $16.3 billion of revenue, in six months [7]. Read the small print, though: $72.4 billion of that loss is an accounting charge on its convertible notes, not cash out the door, and the operating loss was $693 million [7]. The headlines ran with the $80 billion. Accountants read the notes. Be the accountant. At $40 an hour, a $200 agent has to give you back five clear hours a month just to break even. Clear means net: time saved on the jobs it gets right, minus the time you spend checking it, minus the time you spend fixing what it got wrong. That last line is the one the ads leave out.
Take Muse's party trick (Facebook AI, we know what age we are): it phones businesses for you, to book a haircut or check if something's in stock. Some businesses simply hung up when they realised they were talking to a bot. So, TechSpot reported, Meta quietly tested putting human contractors on the line instead, for half its own staff, without clearly telling them. With humans on the line, some tests hit 95% to 98% call success. Meta never said what the AI managed on its own, only that it was lower [17]. Then one contractor made a racist remark on a call about an employee's internet bill, and the test was rolled back. Meta apologised and admitted the lack of disclosure was a mistake. That's not just a scandal, it's a confession. When the call actually had to work, the answer was a human. Just not one anyone was told about, or trained, or supervised. The fix was never "more AI" or "secret humans". It was a human in the loop, out in the open. And OpenClaw's security researchers counted around 18,000 exposed instances, some leaking credentials [19]. Low price, high E. OpenClaw is a bit ETIHS.
The verdict depends on the setup. A developer running a coding agent with approvals on: often NOT SHITE. Someone paying $200 a month for a bot to manage a calendar their phone already manages: you know the word. (Kafka would have loved a bot that books your meetings with the bot that books other people's meetings.)
The toggle tax
Count your tabs right now. Go on. I'll wait. Email, calendar, CRM, accounts, bank, WhatsApp, LinkedIn, a task app, a note-taker, two AI chats and something you opened on Tuesday and are afraid to close.
Every AI start-up wants to be one more of those tabs. One more login, one more subscription, one more inbox of "your agent needs attention". That's how you end up paying for six assistants and still doing the work yourself between them.
So the SHITE Test is strict about S. A simpler tool only counts if you already use it every day. Telling someone "just use a booking app" when it means a new subscription and a new tab isn't a simpler tool, it's another tab. And T gets credit for every subscription the agent lets you cancel. The best agent isn't the cleverest one. It's the one that gets your eyeballs off the other apps.
The same goes for money owed to you. The Banque de France observatory estimated small and micro businesses would have had €13 billion more cash without late payments [21]. Chasing invoices is boring, careful, judgement-heavy work: high H, real I. That's a job worth an agent, as long as a human approves every reminder before it goes out.
Prove it, or it's a brochure
Scoring yourself is a start, but anyone can give themselves a 5. So the test has a measured mode, built on our Brewery mystery shopper, Mysterio. It borrows from the serious open-source work: the UK AI Security Institute's Inspect framework [23], AgentDojo's prompt-injection tests [24] and Sierra's τ-bench idea of pass^k [22]. Pass^k asks the question every manager actually cares about: does it get it right every time, not just once?
Here's how a run works. Pick one job. Write 30 or more real tasks, and hold 30% back so nobody can train for the exam. Run the tool you already use and the agent side by side, three times each. Then throw dirty tricks at it: an invoice with hidden instructions, a request to pay a new bank account, a customer pretending to be the boss. Acting without approval counts as a breach. A bad idea stopped at the approval inbox counts as a caught error. That's the human in the loop doing its job.
We tried it on an invoice-chasing job with two stand-in agents (simple test code, not our real agent, so take the numbers as a demonstration of the bench). Same 40 tasks, same 10 traps.
| Careful (asks first) | Autopilot (just does it) | |
|---|---|---|
| Right every time (pass^3) | 97.5% | 92.5% |
| Safety traps passed | 100% | 10% |
| Net value per month | €448 | −€411 |
| Verdict | NOT SHITE | SHITE (fails E) |
The autopilot looked faster. It was nearly as accurate. And it lost money, because the mistakes that got through cost time to fix and the traps it fell for cost real incidents. Speed without a human in the loop isn't productivity, it's a bill that hasn't arrived yet.
Five questions before you buy (or build) an agent
If you sell agents, ask yourself these first. If you buy them, ask the person selling.
- What one job does it do? Not "transforms your workflow". One job, with a number on it: invoices chased, tickets closed, hours given back.
- What do I already have open that does this? Only count tools you use every day. If the honest answer is your phone, close the tab.
- Who checks it before it acts? Name the human. If the answer is "nobody, that's the point", that's the point where it fails E.
- What does it really cost per month? List price, plus usage, plus your checking time, plus fixing time. Minus the subscriptions you can cancel. If the seller can't tell you, that's your answer.
- Has anyone measured it? On real tasks, more than once, with the dirty tricks included? A demo on stage is not a measurement. Ask the ducks.
Fail any of the five and you'll end up doing the job anyway, plus the extra job of babysitting the agent. That's not automation. That's a second shift.
Our agents aren't for lazy people
The test applies to us too, so we ran it on our own agents first. Four of the agents we had planned for our office hive turned out to be features, not agents. They're still useful, because each one closes a tab, but we stopped calling them agents. That's what an honest test does. It costs you a bit of brochure.
At HI AI Design (Human Intelligence and Artificial Intelligence) our line is simple: our agents aren't for lazy people. It's HI AI for a reason. Humans have to lead: give the agent the right context, bring your own keys, approve what goes out, and adjust the mission when the world changes. It's not fire and forget. Everyone still uses their skills. The agent just takes the boring bits and gives you back the hours.
The SHITE Test is free and open. Score your agent, or one you're thinking of paying for, and see which letter it fails. If you want it measured properly, we'll run the bench on your real tasks and show you the euros per month, not the vibes. This will be available in the next 48 hours on the AI Agent Brewery site.
If you read this far, thank you. Please send me your best ashtray-on-a-motorbike agent stories. I'll grade them, kindly. Drop me a mail at contact@hiai-design.com.
Sources
- Hottest toy for Christmas? NVIDIA CEO plays with Microduck robots, 20,000 sell (TechCrunch, 23 October 2026)
- A protester and a robot duck hiccup: 2 moments from Jensen Huang's keynote (Yahoo News UK)
- Jensen Huang sends in the robot ducks (The Register, 21 October 2026)
- Over 40% of agentic AI projects will be scrapped by 2027, says Gartner (Outlook Business)
- 2026: The State of Consumer AI (Menlo Ventures)
- Consumers want AI shopping help but not AI purchase decisions (Gartner, 27 May 2026)
- Anthropic's IPO prospectus shows $16.3 billion in revenue, an $80.7 billion net loss (Fortune, 26 October 2026)
- Replit AI coding assistant failure (eWeek)
- AI developer Devin gets poor reviews (The Register, 23 January 2025)
- Klarna CEO reverses course by hiring more humans, not AI (Entrepreneur)
- Taco Bell scales back AI tests after customer complaints (Computing)
- Incident 1039: Cursor support bot invents a policy (AI Incident Database)
- The Humane AI Pin is officially dead (Tom's Guide)
- Grok Bot turns agents into persistent digital coworkers (VentureBeat)
- Official Grok Bot breakdown (Vellum)
- Muse agent explained (DataCamp)
- Meta Muse used human contractors for calls (TechSpot)
- OpenClaw API costs: what nobody tells you (ClawdHost)
- OpenClaw security vulnerabilities 2026 (Barrack AI)
- How much time you waste toggling between applications (Canadian Underwriter, reporting Harvard Business Review)
- Rapport annuel 2025 de l'Observatoire des délais de paiement (Banque de France)
- τ-bench: shaping the development and evaluation of agents (Sierra)
- Inspect (UK AI Security Institute)
- AgentDojo (ETH Zurich and Invariant Labs, via PyPI)
- Finland orders Google to stop clearing forest at two data centre sites (The Next Web, 7 October 2026)
- How Big Tech wrote secrecy into EU law to hide data centres' environmental toll (Investigate Europe, 17 April 2026)
- How clean is cleantech from China? (DCVC)
- AI is set to drive surging electricity demand from data centres (International Energy Agency)
- Data centers and water consumption (Environmental and Energy Study Institute)
- Where's Your Ed At (Ed Zitron)
- Microsoft research lays bare the rise of the 'infinite workday' (Workplace Insight, reporting Microsoft's Work Trend Index, June 2025)